Introduction
A production system can face problems at any time. A server may slow down, an application may stop responding, or a sudden traffic spike may affect users. SRE helps teams prepare for these situations and handle them in a clear, measured way.
Site Reliability Engineering combines software development, operations, monitoring, automation, and system management. SRE teams focus on keeping services dependable while helping engineers release changes safely.
Learning SRE takes more than reading definitions. Learners need to understand how systems behave, how teams measure reliability, how engineers investigate incidents, and how automation reduces repeated work.
SRESchool.in focuses on practical SRE learning and introduces important areas such as monitoring, observability, incident management, cloud reliability, automation, and production systems.
What Is Site Reliability Engineering and Why Does It Matter?
Site Reliability Engineering gives engineering teams a structured way to manage reliable software and infrastructure.
An SRE Engineer looks beyond whether an application works during development. The engineer also studies what happens after deployment.
SRE teams commonly work on:
- Service reliability
- Monitoring and alerting
- System performance
- Incident response
- Automation
- Capacity planning
- Cloud infrastructure
- Troubleshooting
- Deployment reliability
- Production operations
SRE matters because users expect services to remain useful when traffic changes, systems fail, or teams release new software.
What Can You Learn Through SRE Training?
SRE Training can help learners understand both technical concepts and practical production work.
A useful SRE Training program can cover:
- Linux and networking basics
- Monitoring and alerting
- Metrics, logs, and traces
- Observability
- SLOs and SLIs
- Error budgets
- Incident management
- Automation
- Cloud platforms
- Infrastructure management
- Capacity planning
- Troubleshooting
- Deployment practices
- Distributed systems
Practical exercises can help learners connect these ideas with real production situations.
What Is SRE Certification and Why Do Professionals Consider It?
SRE Certification gives learners a structured way to demonstrate knowledge of reliability concepts. Different certification providers create different learning goals, exams, and requirements.
A certification may help learners organize their studies and review important SRE topics. However, certification alone does not replace hands-on experience.
An SRE professional also needs to understand systems, investigate failures, work with monitoring data, automate tasks, and respond to production incidents.
Certification requirements and recognition vary by provider and organization, so learners should check the details before choosing a certification.
How to Choose an SRE Course
A useful SRE Course should move from simple concepts toward practical engineering work.
Before selecting a course, check whether it covers:
- SRE fundamentals
- Linux and networking
- Monitoring
- Observability
- SLOs and SLIs
- Error budgets
- Incident response
- Automation
- Cloud systems
- Infrastructure
- Troubleshooting
- Practical projects
A good learning path should also give learners opportunities to practice rather than only memorize definitions.
What Is Site Reliability Engineering Training?
Site Reliability Engineering Training connects reliability theory with daily engineering tasks.
For example, learners can study how an alert works and then examine how engineers respond when that alert appears. They can learn about an SLO and then understand how teams use it to discuss service reliability.
Training can also introduce:
- Production troubleshooting
- System monitoring
- Deployment reliability
- Failure handling
- Automation
- Cloud infrastructure
- Service performance
- Capacity planning
This approach helps learners understand how different SRE responsibilities connect.
Understanding Site Reliability Engineering Certification
Site Reliability Engineering Certification can provide a structured learning target for people studying SRE.
Certification programs may cover topics such as reliability principles, monitoring, service objectives, incident management, automation, and production operations.
Learners should treat certification as one part of professional development. Practical projects, troubleshooting exercises, system knowledge, and real engineering practice also matter.
Each certification provider sets its own curriculum and assessment process, so learners should review those details before making a choice.
How SRE Tutorials Can Help You Learn
An SRE Tutorial can make complex subjects easier to understand by breaking them into smaller lessons.
For example, a tutorial can explain:
- What a service does.
- Which metrics show its health.
- How logs provide useful details.
- How traces show request paths.
- How alerts identify possible problems.
- How SLOs define reliability targets.
- How engineers respond to failures.
- How automation handles repeated tasks.
Short practical tutorials can help beginners build knowledge step by step.
Understanding SRE Tools and Their Uses
SRE Tools help engineers observe, manage, troubleshoot, and automate production systems.
Different environments use different tool combinations. No single tool fits every organization.
Common tool categories include:
- Monitoring tools — Track system and service health.
- Metrics tools — Collect numerical measurements.
- Log management tools — Help engineers examine system and application records.
- Tracing tools — Follow requests across distributed services.
- Observability platforms — Bring different system signals together.
- Alerting tools — Notify teams about important conditions.
- Incident management tools — Help teams coordinate response work.
- Infrastructure tools — Help engineers manage servers and cloud resources.
- Infrastructure as Code tools — Define infrastructure through repeatable configuration.
- Deployment tools — Support controlled application releases.
Tool selection depends on architecture, team needs, technology choices, budget, and operational goals.
What Are SRE Best Practices?
SRE Best Practices help teams create clear and repeatable reliability processes.
Teams often focus on:
- Defining useful SLIs
- Setting meaningful SLOs
- Using error budgets
- Monitoring important services
- Creating useful alerts
- Automating repetitive work
- Preparing for incidents
- Reviewing failures
- Planning system capacity
- Improving deployment processes
Teams should adapt these practices to their own systems. A practice that works for one service may need changes for another.
What Does an SRE Engineer Do?
An SRE Engineer works across software, infrastructure, operations, and reliability.
Daily responsibilities can include:
- Checking system health
- Reviewing monitoring data
- Investigating alerts
- Troubleshooting production problems
- Improving automation
- Supporting deployments
- Managing cloud resources
- Planning capacity
- Improving service reliability
- Responding to incidents
- Reviewing system performance
SRE Engineers often work with developers and infrastructure teams. Their work helps teams understand how software behaves in real production environments.
Understanding SLOs, SLIs, SLAs, and Error Budgets
These four concepts help teams discuss service reliability in measurable terms.
SLI: A Service Level Indicator measures a part of service behavior. Examples include availability, latency, or successful request rate.
SLO: A Service Level Objective sets a target for an SLI. Teams choose targets based on service requirements and business needs.
SLA: A Service Level Agreement describes formal service expectations between parties. It may include reliability commitments and consequences for failing to meet them.
Error Budget: An error budget represents the amount of unreliability a service can tolerate while still meeting its SLO.
These concepts help teams balance reliability work with product changes.
How Monitoring and Observability Help SRE Teams
Monitoring helps engineers see whether something works within expected limits.
Observability goes further by helping engineers investigate why a system behaves in a certain way.
Teams commonly examine:
- Metrics
- Logs
- Traces
- Alerts
- Application performance
- Infrastructure health
- Service dependencies
For example, an alert may show that response time increased. Engineers can then use logs, metrics, and traces to investigate the cause.
Understanding Incident Management and Incident Response
Incidents can affect users, systems, or business operations. SRE teams need a clear process for handling them.
A practical incident response process can include:
- Detecting the problem.
- Understanding the impact.
- Alerting the right people.
- Investigating the cause.
- Restoring the service.
- Communicating important updates.
- Recording the incident.
- Reviewing what happened.
Teams can use post-incident reviews to learn from failures. A useful review focuses on system improvements rather than blaming individuals.
How Automation Can Reduce Repeated Work
Manual work can consume valuable engineering time when teams repeat the same task again and again.
Automation can help with activities such as:
- Deployments
- Infrastructure provisioning
- Health checks
- Backups
- Routine maintenance
- Testing
- Monitoring tasks
- Recovery actions
Engineers should first understand the process before automating it. Poorly planned automation can create new problems instead of removing old ones.
Understanding Cloud Reliability and Distributed Systems
Cloud environments often connect many services, resources, networks, and dependencies.
SRE teams need to understand how these components interact.
Important areas include:
- Resource usage
- Scaling
- Service dependencies
- Network behavior
- Failure handling
- Recovery
- Availability
- Capacity planning
Distributed systems can create complex failure patterns because one service may depend on several other services. SRE practices help engineers identify and manage these dependencies.
How Kubernetes and Terraform Can Support SRE Work
Kubernetes helps teams manage containerized workloads. It can handle tasks such as scheduling workloads, maintaining desired states, and managing services.
Terraform supports Infrastructure as Code. Engineers can describe infrastructure through configuration and manage repeatable infrastructure changes.
Both technologies can support SRE work, but every SRE environment does not require them.
Learners should first understand reliability fundamentals and then explore these tools when their learning goals or project needs make them useful.
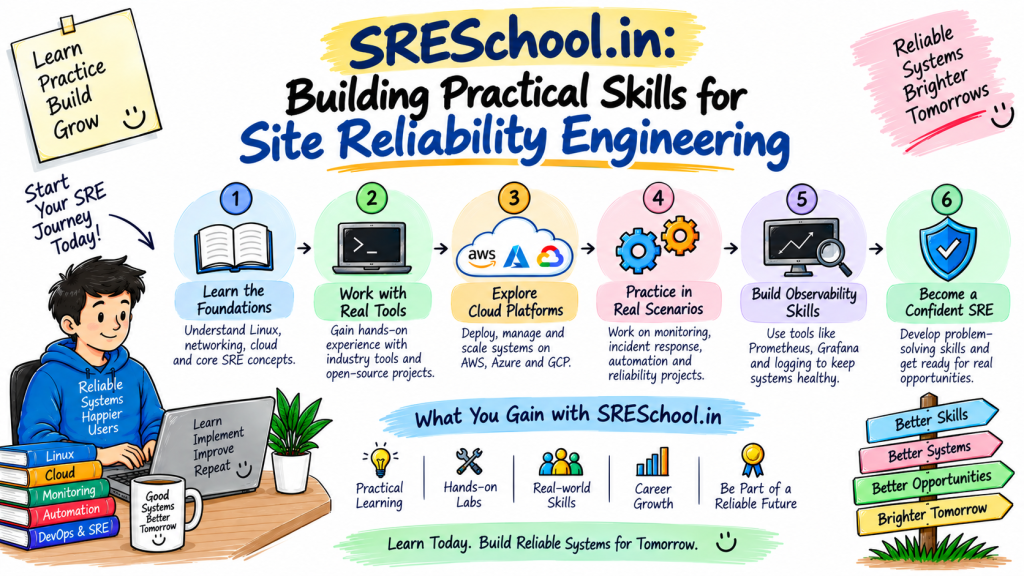
How to Build a Simple SRE Learning Path
A clear learning path can make SRE easier to study.
Step 1: Learn the foundations
Start with Linux, networking, version control, software basics, and infrastructure concepts.
Step 2: Study operations
Move into DevOps, cloud platforms, monitoring, logs, alerts, and observability.
Step 3: Learn reliability concepts
Study SLOs, SLIs, SLAs, error budgets, incident response, troubleshooting, and capacity planning.
Step 4: Practice automation
Work with scripting, infrastructure automation, deployment processes, and repeatable operational tasks.
Step 5: Explore modern infrastructure
Learn Kubernetes, Terraform, cloud systems, and distributed system concepts when they fit your goals.
Step 6: Build projects
Create small projects that combine monitoring, alerts, automation, reliability targets, and incident scenarios.
Understanding SRE Training in India
SRE Training in India can help learners build skills for working with production software and infrastructure.
Learners can focus on practical subjects such as:
- Linux
- Cloud computing
- DevOps
- Monitoring
- Observability
- Automation
- Incident management
- SLOs and SLIs
- Infrastructure
- Troubleshooting
People should compare course content, practice opportunities, learning support, and project coverage before choosing a program.
Job titles, salaries, certification requirements, and hiring expectations vary between organizations. Training providers should not treat these outcomes as automatic results of completing a course.
How SRESchool.in Supports SRE Learning
SRESchool.in focuses on practical learning around Site Reliability Engineering and related production technologies.
The learning approach can help learners explore subjects such as:
- SRE fundamentals
- Monitoring
- Observability
- Incident management
- Automation
- Cloud reliability
- Production systems
- Troubleshooting
- Infrastructure
- Reliability practices
Learners can use these topics to build a stronger understanding of how engineering teams manage services after deployment.
The platform can serve as a learning resource for people who want to study SRE concepts in a structured way and connect those concepts with practical engineering work.
Why Learning SRE Is Becoming More Useful
Software teams need engineers who understand what happens after an application reaches production.
SRE learning brings several areas together. It connects development, operations, infrastructure, monitoring, automation, and reliability.
These skills can help learners understand:
- How systems behave under real conditions
- How teams measure reliability
- How engineers investigate failures
- How automation reduces repetitive work
- How cloud systems support applications
- How teams prepare for incidents
- How reliability affects deployment decisions
The field also encourages engineers to think about measurable outcomes instead of relying only on assumptions.
Frequently Asked Questions About SRESchool.in
Which subjects does SRESchool.in cover?
SRESchool.in focuses on SRE concepts such as monitoring, observability, automation, incident management, cloud reliability, and production systems.
What can a learner expect from SRE Training?
Learners can study reliability concepts and practice skills related to monitoring, troubleshooting, automation, incidents, infrastructure, and system performance.
Can a beginner start with SRE?
Yes. Beginners can start with Linux, networking, software, and infrastructure basics before moving into deeper SRE topics.
How does SRE Certification fit into learning?
Certification can provide structured study goals, but practical skills and hands-on experience remain important parts of SRE development.
Where does an SRE Engineer usually work?
An SRE Engineer can work across software development, cloud infrastructure, operations, platform engineering, and production systems.
Which tool categories matter in SRE?
Monitoring, metrics, logging, tracing, alerting, incident management, infrastructure, automation, and deployment tools commonly support SRE work.
Why do teams define SLOs?
Teams define SLOs to create measurable reliability targets and make clearer decisions about service performance and engineering work.
When does observability become useful?
Observability becomes especially useful when engineers need to investigate complex system behavior and understand possible causes behind an issue.
Does Kubernetes fit every SRE environment?
No. Kubernetes can support teams that manage containerized workloads, but organizations should choose technologies based on their actual architecture and needs.
How can learners practice after studying SRE?
Learners can build small projects involving monitoring, alerts, SLOs, automation, incident scenarios, cloud infrastructure, and troubleshooting.
Final Thoughts
For anyone exploring SRE, practical learning can create a stronger foundation than memorizing isolated definitions.
Start with basic infrastructure and operations knowledge. Then study monitoring, observability, SLOs, incident response, automation, cloud reliability, and distributed systems.
SRESchool.in can support this learning journey by bringing important SRE topics into one practical learning path. The goal should remain clear: understand how production systems work, measure their reliability, respond to problems, and improve them through better engineering practices.